Posts about Data Engineering
Practical data engineering: ingestion pipelines, repartitioning, open table formats and lightweight data platforms built with DuckDB and cloud services.
8 posts
Filter by tag
Filter by tag:
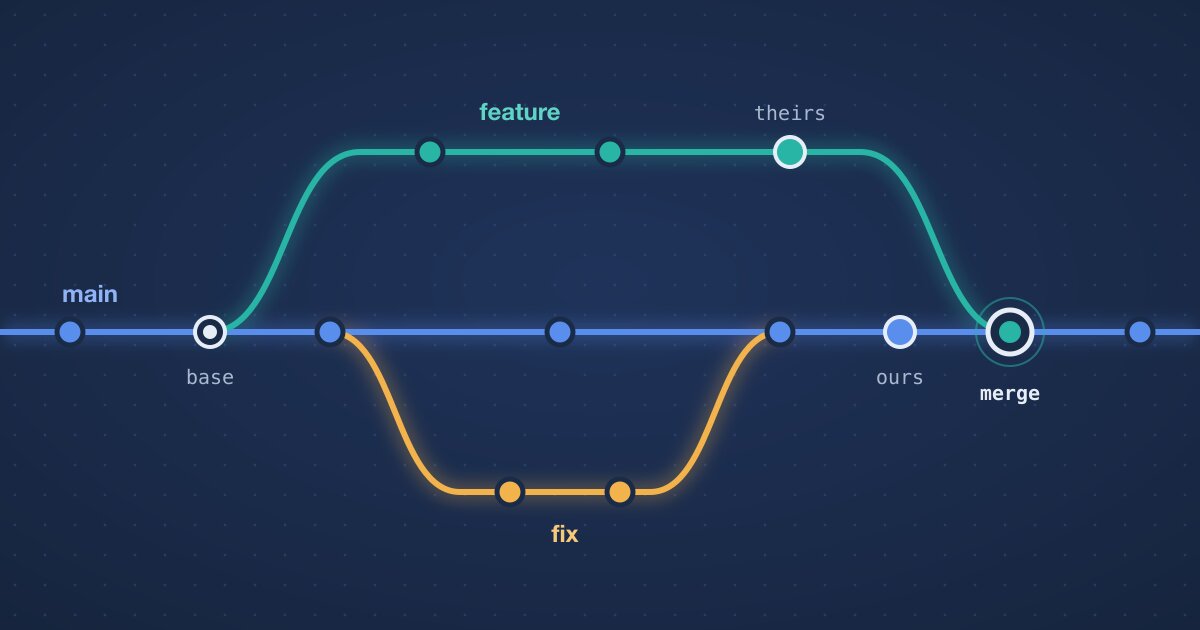
Merges for DuckDB branches and snapshots
differential 1.1 brings three-way merges to DuckDB: merge branches and snapshots, fast-forward, resolve typed conflicts with a table, merge schemas, use S3.
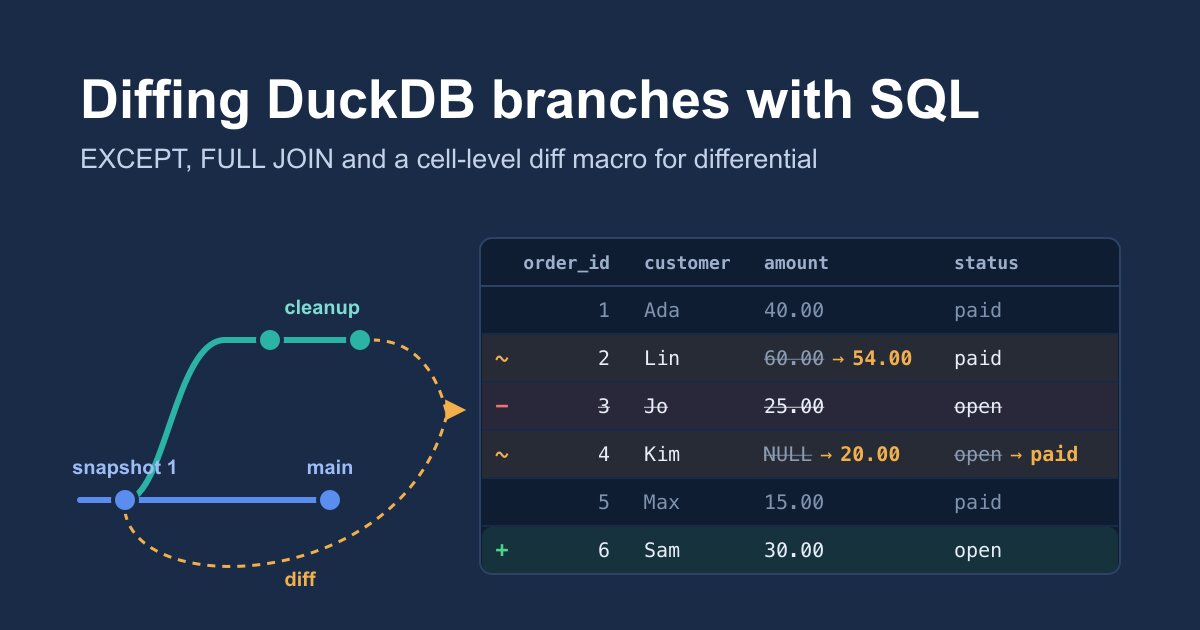
Diffing DuckDB branches and snapshots with plain SQL
Diff DuckDB branches and snapshots with plain SQL: EXCEPT, a keyed FULL JOIN, changed columns and a reusable cell-level diff macro for differential.
Versioned DuckDB databases, locally or replicated through S3, for people and agents
differential extension for DuckDB 2.0: snapshots, branches and time travel locally, plus leader/follower replicas, failover and shared writers via S3.
Differential storage for DuckDB
Add snapshots, time travel and writable branches to native DuckDB databases from SQL with duckdb-differential, and publish versions to S3.
Introducing polyglot - A Rust/Wasm SQL transpilation library
polyglot transpiles SQL between 33 dialects like PostgreSQL, BigQuery and Snowflake. A Rust port of sqlglot, compiled to Wasm to run in the browser and Node.js.
Handling GTFS data with DuckDB
Load GTFS public transit schedule feeds into a DuckDB database, query stops, routes and trips with SQL, and export the data to Parquet.
Using DuckDB-WASM for in-browser Data Engineering
Analyze, transform and visualize local and remote data in the browser with DuckDB-WASM and SQL Workbench, including a full example data engineering pipeline.
Gathering and analyzing public cloud provider IP address data with DuckDB & Observable
Unify, clean and analyze the published IP address ranges of AWS, Azure, Google Cloud, Cloudflare, Oracle, DigitalOcean and Fastly with DuckDB and Observable.